This article may contain affiliate links. We may earn a small commission if you purchase through our links, at no extra cost to you. We only recommend tools we’ve personally tested.
Affiliate Disclosure: Some links in this article are affiliate links. If you make a purchase through these links, we may earn a commission at no additional cost to you. We only recommend tools we actively use and trust.
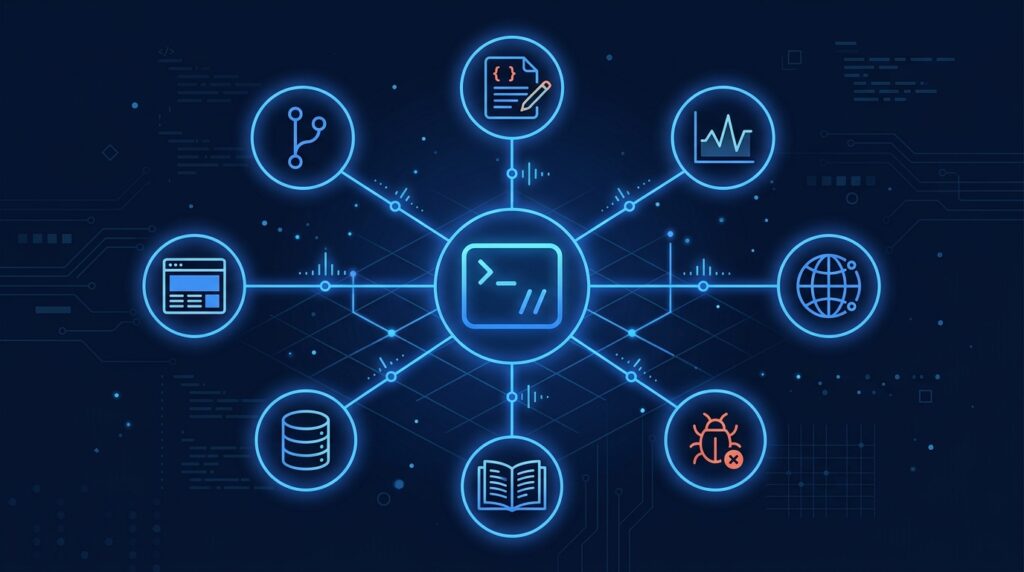
Claude Code out of the box can read, write and run things on your machine. An MCP server gives it hands outside the machine: your GitHub issues, a real browser, your production database, your error tracker, the live web. The Model Context Protocol is the plug standard; a server is one thing plugged in.
The catch is that every server you add costs context and attention. Fifty tools from six servers is how you get an agent that spends its first thousand tokens deciding which search tool to use. Since Claude Code 2.1.232 tool search is on by default — servers are discovered lazily and connected on first use — which takes most of the sting out, but the rule still holds: install the servers whose job you can name, remove the ones you cannot.
These are the eight that stay installed across our projects, what each is for, and the exact command to add it. If you want to write your own, we have a separate guide on how to build an MCP server.
Thirty seconds on how adding works
Three transports, one command:
claude mcp add --transport http github https://api.githubcopilot.com/mcp/

# Local (stdio) server — everything after -- is the server's own command
claude mcp add --transport stdio playwright -- npx -y @playwright/mcp@latest

# Check what's connected
claude mcp list
Scope matters. The default local scope is you-only, this-project-only. --scope project writes to .mcp.json so your team gets the server from git; --scope user follows you across every project. Remote servers that need a login get it through /mcp inside Claude Code (OAuth in the browser) or claude mcp login .
A server’s tools appear to Claude as mcp__, which is also what you match on if you want a hook to guard them.
1. GitHub (official)
For: issues, pull requests, code search, CI status — without leaving the terminal.
claude mcp add --transport http github https://api.githubcopilot.com/mcp/
Then /mcp to authenticate. The payoff is in the workflow, not any single tool: “look at issue #412, reproduce it, fix it, open a PR that references it” becomes one prompt. It also makes Claude far better at code review, because it can read the PR’s discussion rather than just the diff. If your engineers live in Linear or Jira instead, those have official remote servers too; pick the one that is your source of truth and skip the other.
2. Playwright (official, Microsoft)
For: letting Claude verify its own UI changes in a real browser.
claude mcp add --transport stdio playwright -- npx -y @playwright/mcp@latest
This is the server that changed how we build front ends with an agent. Claude edits a component, loads the page, clicks through the flow, reads the accessibility tree and the console, and fixes what it broke — before telling you it is done. Pair it with a Stop hook that insists on a passing run and you have a self-checking loop. It drives a headless Chromium by default; add --headed to the args if you want to watch.
3. Context7
For: version-correct documentation, on demand, instead of hallucinated APIs.
claude mcp add --transport http context7 https://mcp.context7.com/mcp
Models are trained on a snapshot; libraries move on. Context7 indexes real, current docs and injects the relevant section when Claude asks — so a prompt like “use the Next.js 15 app router caching API, check context7” produces code that matches the version in your package.json rather than the one in the model’s memory. Free tier is enough for an individual developer.
4. Firecrawl
For: live web data as clean markdown or structured JSON — search, scrape, crawl, map.
claude mcp add --transport stdio firecrawl --env FIRECRAWL_API_KEY=fc-your-key -- npx -y firecrawl-mcp
Claude Code has a basic web fetch, but it falls over on JavaScript-rendered pages, bot walls and anything beyond one URL. Firecrawl’s server exposes its whole API as tools: scrape a page to markdown, crawl a documentation site, map a domain’s URLs, search the web and get the content of the results back in one call. We use it for competitor research, pulling changelogs, and feeding agents data that is not in any API. It needs an API key; the free plan covers a few hundred pages a month, which is plenty to find out whether you need more.
5. A database server (Postgres / DBHub)
For: letting Claude look at the real schema and real data before it writes a migration or a query.
claude mcp add --transport stdio db -- npx -y @bytebase/dbhub --dsn "postgresql://user:pass@localhost:5432/app?sslmode=disable"
DBHub speaks Postgres, MySQL, SQL Server and SQLite. The difference between “write a query for orders by region” with and without schema access is the difference between working SQL and plausible SQL. Two rules: point it at a read replica or a dev database, never production with write credentials; and put the DSN in an environment variable (${DB_URL} expands inside .mcp.json) rather than committing it.
6. Sentry (official)
For: debugging production errors from the stack trace instead of from a Slack screenshot.
claude mcp add --transport http sentry https://mcp.sentry.dev/mcp
“Find the most frequent new error in the last 24 hours, show me the trace and the release it started in, then find the commit” is a ten-minute human task and a one-prompt agent task once Sentry is a tool. Authenticate through /mcp. If you use a different error tracker, check whether it has a remote MCP endpoint — most of the major ones shipped one this year.
7. Memory (official reference server)
For: facts that should survive the session: decisions, conventions, who owns what.
claude mcp add --transport stdio memory -- npx -y @modelcontextprotocol/server-memory
A small local knowledge graph. It is deliberately simple, which is why it works: Claude stores an entity and a few relations, and reads them back next session. We keep project-level knowledge in CLAUDE.md (it is versioned and reviewable) and use the memory server for the softer, accumulating kind — “the staging database is refreshed from prod on Mondays”, “the lead reviewer prefers tables to bullet lists”. A SessionStart hook that reminds Claude to check memory first makes it stick.
8. Notion (official) — or wherever your specs live
For: reading the ticket, the PRD, the runbook, without pasting them.
claude mcp add --transport http notion https://mcp.notion.com/mcp
The point generalises: whatever holds the why behind the code — Notion, Confluence, Google Docs — give the agent read access to it. Code written from the actual spec needs far fewer correction rounds than code written from your summary of the spec. Keep it read-mostly; an agent that edits your docs as a side effect is a surprise nobody enjoys.
Servers we tried and removed
- Filesystem server — redundant; Claude Code’s built-in Read, Edit, Glob and Grep are better and permission-aware.
- Generic “fetch” server — superseded by the built-in fetch for simple pages and Firecrawl for everything else.
- Slack — great for a bot, noisy for a coding agent. Notifications go the other way: a
Notificationhook that pings you when Claude is waiting. - Everything-in-one “agent toolkit” servers with 80+ tools — tool search helps, but it is still a lot of surface area for a few features you use.
Keeping it sane
- Project vs user scope. Servers that depend on the repo (database, Playwright config) go in
.mcp.jsonwith--scope project. Personal ones (memory, Notion) go in--scope user. - Secrets in environment variables.
.mcp.jsonexpands${VAR}and${VAR:-default}; commit the file, not the keys. - Output limits. MCP tool output is capped at 25,000 tokens by default (
MAX_MCP_OUTPUT_TOKENSraises it). Acrawlthat returns a whole site will be truncated — map first, then scrape what you need. - Long calls background automatically. Anything over two minutes moves to a background task since 2.1.212; you do not need to babysit a crawl.
- Hosting your own. Remote servers your whole team uses are easiest to run on a small VPS behind HTTPS with a bearer token; a DigitalOcean droplet at a few dollars a month is more than enough for an MCP endpoint.
- Guard the dangerous ones. A
PreToolUsehook matchingmcp__db__.*that denies anything containingDELETEorDROPcosts nothing and has saved us once already. See the hooks guide.
Start with GitHub and Playwright. Add Context7 the first time Claude invents an API. Add the rest when you can name the job.
